Improving the Developer Experience by Monitoring Third-Party Outages


Introduction
The role of third-party SaaS and cloud services in the modern software development stack needs no explanation. Primarily due to the ease of setting and hooking them up together, they make the software development lifecycle (SDLC) much easier than it was 10 years ago. No more managing the overhead of installing, configuring, maintaining, backing up, and scaling of source code repos, virtual machines, and CI/CD systems. Some SaaS services don't have any in-house options, e.g. payment gateways, so you have to use them.
This dependency on third-party services also brings risks. The more such services in the chain, the more likely it is that a failure in one of them will impact or even cripple your smoothly running development and deployment pipeline. These failures by extension will also impact your business and customers.
You have vetted and chosen reliable services. However, outages happen. The best you can do is to prepare for them and know when they occur. This article is about the knowing part.
- Introduction
- The Role of Third-Party Services
- The Impact of Third-Party Outages
- Monitoring Third-Party Service Outages
- Best Practices
- Conclusion
- Summary
The Role of Third-Party Services
A typical software development organization has many third-party services:
- Infrastructure
- DNS
- Cloud Provider
- PaaS
- Content Delivery Network
- Monitoring
- Observability
- On-call management
- Communication and Collaboration
- Chat
- Office suites
- Development and Operations
- Source Code Repositories
- CI/CD
- Artifact repositories
- LLM APIs
- Auth APIs
- Artifact repositories
- Project management
- Product-function related SaaS
- Payment gateways
- SMTP Providers
- Other product functions
- Marketing
- Customer support and ticketing
- Analytics
It's not uncommon to have more than 100+ third-party services. According to the 2025 State of SaaS report, companies use an average of 106 SaaS apps. Knowing when a service is unavailable is important to many folks, including your development and operations teams. Your product reliability depends directly on external services.
The Impact of Third-Party Outages
Recently, somebody asked me:
"So what if you know that a service is down? What is the point of knowing if you cannot do anything about it?"
Sounds logical.
However, the question assumes that it is easy to determine which service is experiencing an outage. So let me break that down:
- It's hard to know which of your hundreds of dependencies has an outage. The problem of checking different status pages, support forums, social media, and so on explodes when you have to do it for 10+ services. If you have just 1 or 2, it's easy to check.
- There is something you can do about it. Once you know that a particular service has an outage, you can save your team hours of debugging and troubleshooting. IncidentHub was born out of such personal experiences in my past roles where I doubled as a backend dev and Ops engineer. I could see the impact that a GitHub outage had on my dev team (PRs stuck, builds failing), and also the impact that a Slack outage had on my sales team (lost/delayed messages, anyone?). And nobody knew why. The status pages had the answers all along.
The real cost here is the waste of developer time and customer escalations.
Who is Impacted?
Third-party services can directly impact you and your team.
- If you are a SaaS vendor, your product's reliability is dependent on the reliability of the third-party services it uses.
- If you provide mobile/web app development services, your ability to deliver on time depends on the availability of your third-party vendors.
Knowing which services are down - and when they are back up - is better than being in the dark about the fact that an external service has caused a problem.
Monitoring Third-Party Service Outages
How Can I Monitor Third-Party Dependencies During an Incident?
If you have third-party incident tracking as part of your incident management process, you have already taken the first step. The most common way to track third-party outages is to check their status pages. But how do you track hundreds of status pages?
Tracking Status Pages Manually
Manual monitoring of status pages is fraught with challenges:
- Status page providers can change and break existing subscriptions and notifications without warning.
- Many status pages offer RSS feeds only without component/region filtering, forcing you to drown in alert noise.
- Manual monitoring of 100+ status pages is not practical.
- Some status pages lack feeds or subscription options.
- Status page URLs can change, leaving you unaware of outages.
- DIY solutions like pushing RSS feeds into Slack lack filtering capabilities, can break when status pages change, and are an ongoing maintenance burden on your teams.
Tracking Status Pages with a Status Page Aggregator
A status page monitor/aggregator can simplify the process of tracking status pages.
A status page aggregator like IncidentHub:
- Offers a single normalized view across cloud providers' status pages.
- Hides the complexity of different status page formats.
- Detects and adjusts to changing status page formats over time.
- Let's you choose the notification mode you want for alerts.
- Offers notification modes not available on the status page.
- Let's you analyze historical data and availability trends.
When you use a status page aggregator, you can choose to receive only those alerts that are relevant. Depending on your team's needs, you can push the alerts to any of the following:
- A Slack channel.
- A Discord channel.
- A custom webhook that integrates with your internal dashboard.
- A team email address.
- A Microsoft Teams channel.
- A Zendesk workspace.
- A custom integration using APIs.
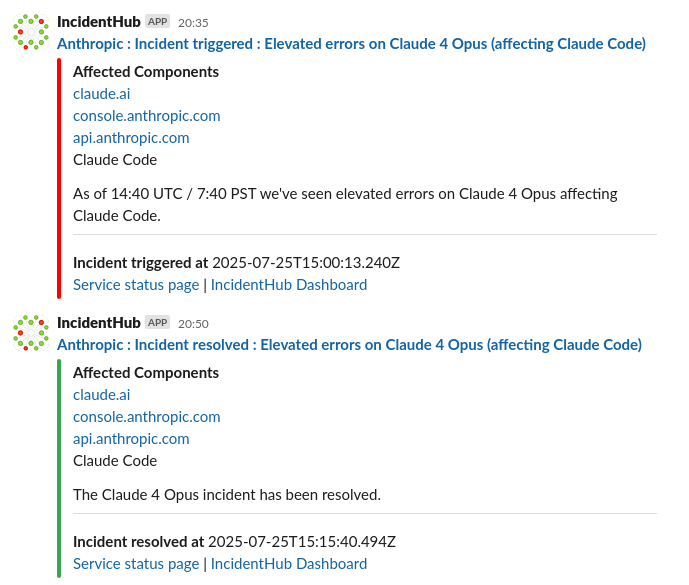
Another option if you choose not to receive alerts is to put up a unified status page on a large screen TV or monitor. It shows you the overall status of all your third-party dependencies at a glance.
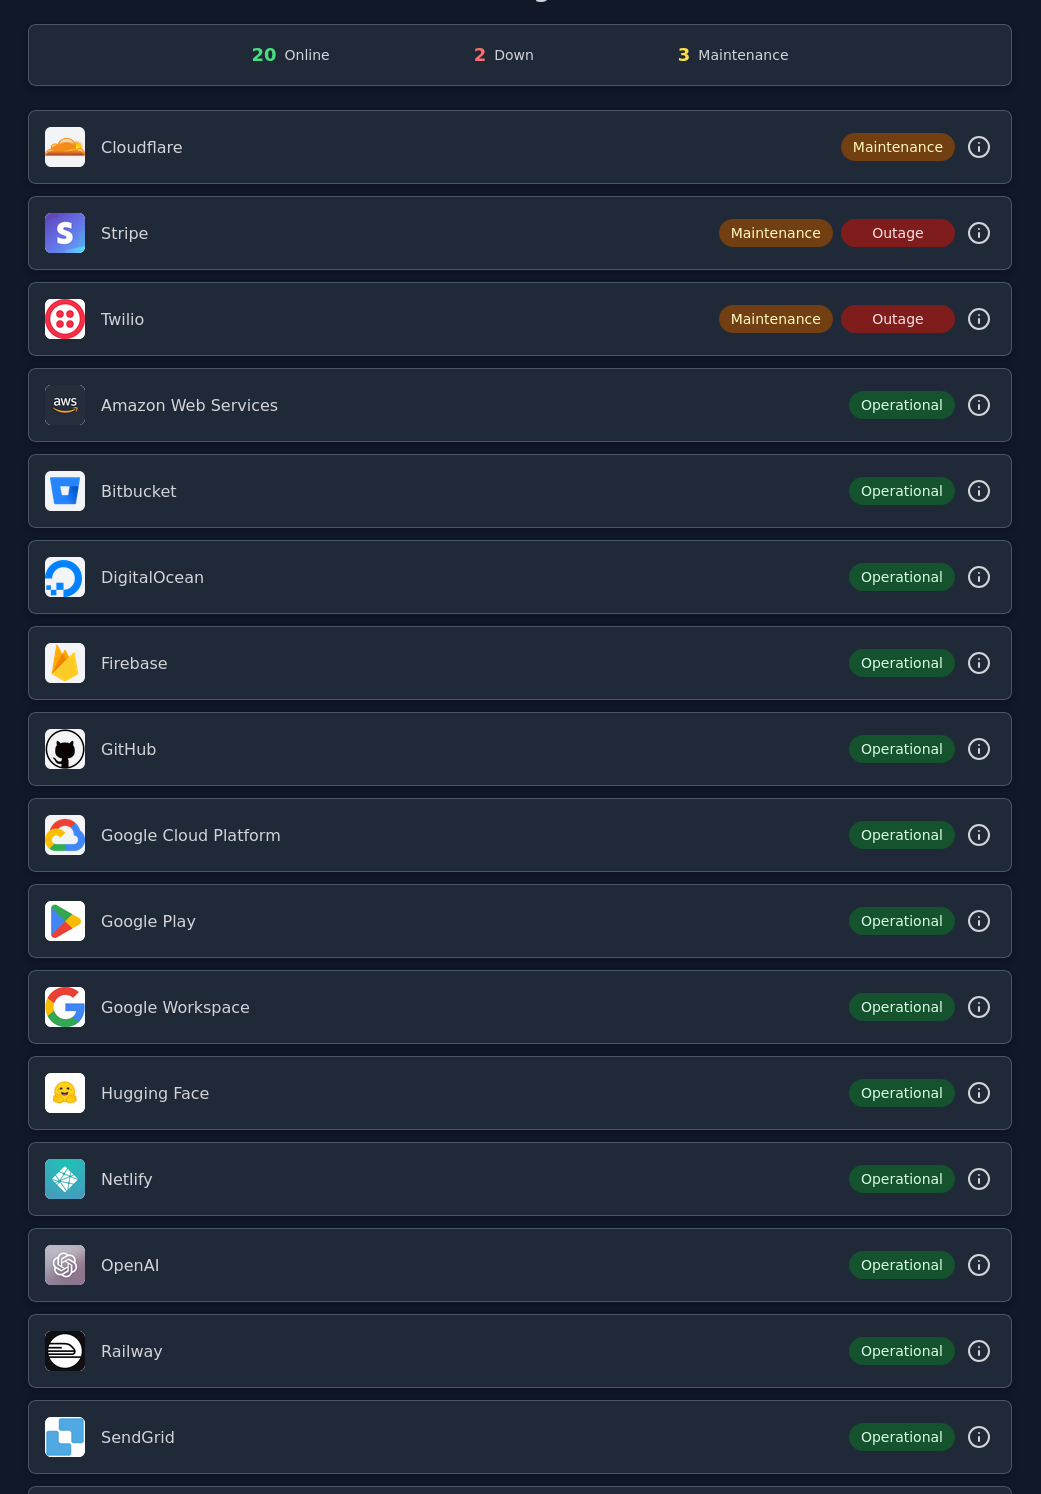
Overall, a better developer experience.
Check out this short video tutorial on how to set up a unified status page with all your third-party services with a status page aggregator.
Best Practices
If you are monitoring third-party services using a status page aggregator like IncidentHub, there are a few best practices you should follow:
- Fine-tune your alerts so that your team is not overwhelmed by alert fatigue.
- Check in with your team periodically to see if they are seeing value from the alerts. If not, a unified status page displayed prominently might be better suited for your team.
- Periodically ensure that the list of monitored services and components is up to date.
- Include third-party service outages in your incident response plan.
Conclusion
Third-party services form a key part of your software development stack. Knowing when a service is down is important to many folks, including your development and operations teams. A status page aggregator like IncidentHub can help you track third-party outages and let's you focus on product development.
Summary
| Aspect | Description |
|---|---|
| Problem | Modern software development relies heavily on 100+ third-party services, making it difficult to track outages across all dependencies. |
| Impact | Third-party outages waste developer time and cause customer escalations when teams don't know which service is down. |
| Manual Tracking Challenges | Status page monitoring manually is impractical due to changing formats, lack of filtering, too many pages, and maintenance burden. |
| Solution | Status page aggregators like IncidentHub provide unified tracking across all third-party services. |
| Benefits | Single normalized view, automated alerts, historical data analysis, and customizable notification channels. |
| Implementation | Can be integrated via Slack, Discord, webhooks, or displayed on unified status dashboards. |
You might also like:
- Top 6 Reasons Why You Need a Status Page Aggregator
- Product Update - Public Status Pages
- A Step by Step Guide to Checking if a SaaS is Down
This article was originally published on the IncidentHub blog.
All product names, company names, logos and trademarks are the property of their respective owners.
Photo credits: SEO Galaxy on Unsplash